Short answer
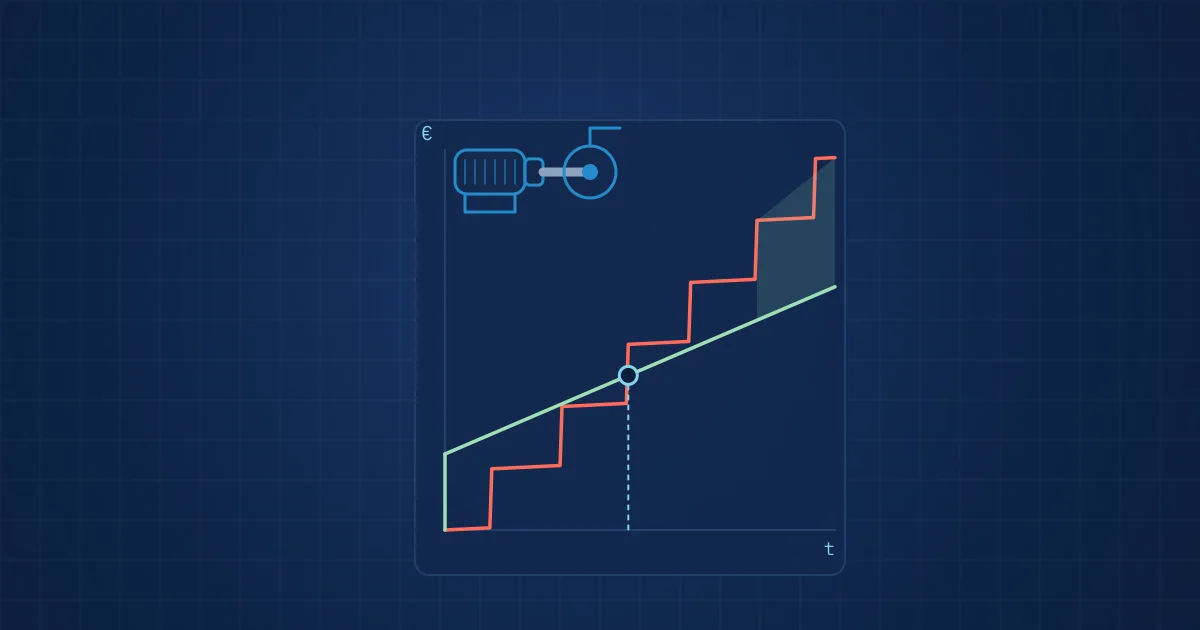
Predictive maintenance ROI for pumps and motors depends on four plant-specific numbers: how often assets fail unexpectedly, what an unplanned failure costs compared with a planned repair, what share of failures monitoring catches early, and how many false alarms it raises. Multiply avoided cost by caught failures, subtract false-alarm cost, and you have the yearly budget monitoring must beat.
Key takeaways
- The benefit of predictive maintenance is avoided cost per caught failure times the number of failures caught, minus the cost of false alarms.
- Turning the calculation round into a break-even monitoring budget per asset avoids arguing about vendor prices and makes the decision transparent.
- In our illustrative example, a critical pump fleet supports roughly 1,750 euros per asset per year, while non-critical pumps without production impact support under 250 euros.
- Widely quoted industry averages, such as a tenfold ROI, come from older, unnamed surveys and should be treated as context at most, not as inputs.
Predictive maintenance ROI is usually presented as a single impressive number. That number rarely survives contact with a plant controller. A calculation that does survive is built from the plant's own failure history and cost structure, states every assumption, and shows how the result moves when an assumption is wrong.
This article builds that calculation for pumps and their drive motors, which are among the most common monitored assets in process and utility plants. The worked example uses invented but plausible numbers and is clearly labelled as illustrative. Replace them with yours.
What the published numbers say, and why not to use them directly
The most cited figures come from the US Department of Energy's Operations and Maintenance Best Practices Guide, Release 3.0 (August 2010, prepared by Pacific Northwest National Laboratory). It cites past studies estimating that a properly functioning predictive maintenance programme saves 8 to 12 percent over preventive maintenance alone, and says that plants relying heavily on reactive maintenance could see savings above 30 to 40 percent. It also quotes "independent surveys" giving a return on investment of 10 times, 25 to 30 percent lower maintenance costs, 70 to 75 percent fewer breakdowns and 35 to 45 percent less downtime. The guide does not name these surveys, and we have not been able to trace the figures to a primary study.
Those figures are useful context. They are also averages from unnamed surveys, from a different decade and a different labour and energy market. The same guide is candid about the downside: start-up costs for diagnostic equipment and training, and savings that are not readily visible to management. Use the averages to decide whether a closer look is worthwhile, then do the closer look with your own data.
Two facts from authoritative sources do justify paying attention to motors. The DOE guide states that bearing failures account for nearly half of all motor failures, which is precisely the failure mode vibration monitoring sees best. And the European Commission's energy-efficient products page on electric motors puts motor systems at more than half of EU electricity consumption, which is why the Ecodesign rules in Regulation (EU) 2019/1781 apply to them.
The four inputs that decide predictive maintenance ROI
Failure rate (lambda). Unplanned failures per asset per year, from your maintenance records. Count only failures that a condition monitoring technique could plausibly have seen coming: bearing, alignment, imbalance, cavitation, lubrication and cooling problems. Seal leaks found by an operator or electrical trips from upstream events do not belong here.
Cost of an unplanned failure (C_u). Repair cost at reactive rates, including overtime, expedited parts and secondary damage, plus the cost of lost or scrapped production. For many pumps the second part dominates.
Cost of a planned intervention (C_p). What the same repair costs when caught early: a bearing change in a planned window, standard parts, no production loss.
Catch rate (p). The share of relevant failures that monitoring detects with enough lead time to plan the repair. This is the most uncertain number and the one vendors most like to round up. It depends on the failure mode, the sensor, the measurement interval and the quality of the models and people interpreting the data.
Add one cost that business cases often forget: false alarms (F per year, each costing C_f) for investigation, an unnecessary stop or a technician's afternoon.
The formula
Annual net benefit before monitoring costs:
B = N x lambda x p x (C_u - C_p) - F x C_f
where N is the number of monitored assets. Divide B by N and you have the break-even monitoring budget per asset per year: the most you can spend on sensors, software, connectivity, model work and the people who act on alerts, and still come out even.
We prefer this framing to a classic ROI percentage. It separates the plant's economics, which you know, from the monitoring price, which you can then compare against any offer.
Illustrative worked example: 24 pump-motor sets
The numbers below are invented for illustration. They are not data from a NeuroControls customer, and they are not a quote.
| Assumption (illustrative) | Value |
|---|---|
| Monitored pump-motor sets, N | 24 |
| Relevant unplanned failures per set per year, lambda | 0.25 (six failures a year across the fleet) |
| Reactive repair cost | 6,000 euros |
| Production loss per unplanned failure | 8 hours at 1,500 euros per hour = 12,000 euros |
| Cost of an unplanned failure, C_u | 18,000 euros |
| Cost of a planned repair, C_p | 3,500 euros |
| Catch rate, p | 50 percent |
| False alarms per year, F | 4 |
| Cost per false alarm, C_f | 400 euros |
Working through it:
- Relevant failures per year: 24 x 0.25 = 6.
- Failures caught early: 6 x 0.5 = 3.
- Avoided cost per caught failure: 18,000 - 3,500 = 14,500 euros.
- Gross avoided cost: 3 x 14,500 = 43,500 euros.
- False alarm cost: 4 x 400 = 1,600 euros.
- Net benefit B: 43,500 - 1,600 = 41,900 euros per year.
- Break-even budget per asset: 41,900 / 24 = about 1,746 euros per asset per year.
If the full cost of monitoring these 24 sets, including installation spread over its useful life and the hours your team spends on alerts, stays well below about 41,900 euros a year, the programme pays. If it does not, no amount of enthusiasm will fix the business case.
Sensitivity: which assumption moves the answer
The base case looks comfortable. The table shows what happens when single assumptions change, everything else held constant.
| Scenario (illustrative) | Caught failures per year | Net benefit B | Break-even per asset |
|---|---|---|---|
| Base case | 3.0 | 41,900 euros | about 1,746 euros |
| Catch rate 30 percent | 1.8 | 24,500 euros | about 1,021 euros |
| Catch rate 70 percent | 4.2 | 59,300 euros | about 2,471 euros |
| Failure rate 0.05 per set per year | 0.6 | 7,100 euros | about 296 euros |
| No production loss (C_u = 6,000 euros) | 3.0 | 5,900 euros | about 246 euros |
| 12 false alarms per year | 3.0 | 38,700 euros | about 1,613 euros |
Three lessons follow:
- Production loss is the lever. Remove it and the same fleet barely justifies monitoring. That is why redundant pumps with automatic changeover are rarely worth continuous monitoring, while a single feed pump on a continuous line almost always is.
- Failure rate matters as much as catch rate. A fleet that rarely fails gives monitoring little to catch. Reliable assets may be better served by periodic route-based measurements.
- False alarms are cheap until they are not. Their direct cost is modest here. The indirect cost, a team that stops trusting alerts, is what destroys programmes. Self-monitoring sensors and severity grading exist to keep that number down.
Getting the inputs right
A checklist for building a credible case:
- Pull three to five years of work orders for the candidate assets and classify each failure by mode.
- Exclude failure modes that the planned sensors cannot see.
- Get the production loss figure from operations, not maintenance, and agree it with finance.
- Estimate catch rate per failure mode, conservatively, and justify it with a pilot where possible.
- Include the internal labour to review and act on alerts, not just the hardware.
- Revisit the numbers after the first year, using actual caught failures and false alarms.
ISO 17359:2018 gives general guidelines for setting up a condition monitoring programme for machines, and is a good structure for the steps above. If you plan to go further into remaining-life estimates, ISO 13381-1:2025 provides guidance and requirements for prognostics.
Which techniques fit pumps and motors
For most pump-motor sets, vibration carries the largest share of detectable failure modes: bearings, imbalance, misalignment, looseness and cavitation-related broadband noise. Our introductions to vibration analysis and bearing fault frequencies cover the signal side. Thermal imaging adds overloaded motors, blocked cooling and electrical connection problems, as described in our thermal imaging guide. Airborne sound and ultrasound add lubrication and leakage. Each technique raises the catch rate for some failure modes, which is the term in the formula that monitoring actually controls.
How NeuroControls approaches this
We do not publish ROI figures for our systems, because the honest answer depends on the four plant numbers above. What we can influence is the catch rate and the false-alarm rate. Our engineers train models on customer data that go from anomaly detection to fault classification and severity grading, as explained in our post on the model ladder. Each sensor reports its signal health and dropouts with its data, so dropouts are flagged rather than read as machine data.
The Machine Health Kit combines an Edge AI Hub with Vibration and Acoustic Nodes and is built to order. If you want to run the calculation above for your own assets before talking about hardware, the condition monitoring solution page shows how we start, and you can contact us to request a quote for a pilot.
Frequently asked questions
How do you calculate predictive maintenance ROI?
Estimate the yearly number of relevant unplanned failures, the cost of each failure compared with a planned repair, the share of failures monitoring will catch early and the cost of false alarms. Net benefit equals assets times failure rate times catch rate times avoided cost per failure, minus false-alarm cost. Compare that benefit with the full annual cost of monitoring.
What is a typical ROI for predictive maintenance?
There is no reliable typical figure. The US Department of Energy's O&M Best Practices Guide (2010) cites past studies estimating 8 to 12 percent savings over preventive maintenance alone. It also repeats a tenfold return from surveys it does not name, which we could not trace to a primary study. Real results vary widely with failure rates, production loss per failure and how well alerts are acted on, so a plant-specific calculation is the only reliable answer.
Is predictive maintenance worth it for small pumps?
Often not as continuous monitoring. If a pump has a redundant standby, fails rarely and causes no production loss, the avoided cost per caught failure is small and the break-even monitoring budget drops to a few hundred euros per year or less. Periodic route-based measurements or simple run-to-failure with spares may be more economical.
Which failures in pumps and motors can condition monitoring detect?
Vibration monitoring detects bearing defects, imbalance, misalignment, looseness and some cavitation effects. Thermal imaging adds overloads, cooling problems and poor electrical connections. Acoustic and ultrasonic monitoring add lubrication problems and leaks. The DOE notes that bearing failures account for nearly half of motor failures, which makes bearings the main target.
How do false alarms affect the business case?
Each false alarm costs investigation time and sometimes an unnecessary stop, which reduces net benefit directly. The larger cost is indirect: if alerts are often wrong, teams stop responding and caught failures fall. Sensors that report their own health, severity grading and periodic review of alarm statistics help keep false alarms low.
Sources and further reading
- US DOE FEMP / PNNL: Operations and Maintenance Best Practices Guide, Release 3.0 (2010)
- European Commission: Energy-efficient products - Electric motors
- ISO 17359:2018 Condition monitoring and diagnostics of machines - General guidelines
- ISO 13381-1:2025 Condition monitoring and diagnostics of machine systems - Prognostics - Part 1